Analysis of categorical data with R: Categorical data analysis is a fundamental aspect of statistical modeling, often used when the variables in a dataset are qualitative rather than quantitative. Examples of categorical data include gender, marital status, survey responses, or any variables that describe characteristics rather than quantities. R, with its robust libraries and powerful statistical tools, is a popular choice for analyzing such data. This article delves into the methods and techniques used for analyzing categorical data using R, providing practical examples and insights.
Understanding Categorical Data
Categorical data can be divided into two main types:
Nominal Data: These variables have no intrinsic ordering. Examples include colors (red, blue, green) or types of animals (cat, dog, bird).
Ordinal Data: These variables have a meaningful order but the intervals between values are not uniform. Examples include satisfaction ratings (poor, fair, good, excellent) or education levels (high school, college, graduate).
Before analysis, data must be properly formatted and cleaned. For categorical data, this often involves encoding text labels into factors.
# Example: Creating a factor in R
data <- data.frame(
  Gender = c("Male", "Female", "Female", "Male"),
  AgeGroup = c("Young", "Adult", "Senior", "Young")
)
data$Gender <- factor(data$Gender)
data$AgeGroup <- factor(data$AgeGroup, levels = c("Young", "Adult", "Senior"))
2.Exploratory Data Analysis (EDA)
EDA helps in understanding the structure and distribution of data. For categorical variables, bar plots and frequency tables are commonly used.
# Frequency table
table(data$Gender)

# Bar plot
barplot(table(data$AgeGroup), col = "skyblue", main = "Age Group Distribution")
3.Contingency Tables
Contingency tables (cross-tabulations) are used to examine the relationship between two or more categorical variables.
# Creating a contingency table
table(data$Gender, data$AgeGroup)
Chi-square tests can be applied to contingency tables to test the independence between variables.
# Chi-square test
chisq.test(table(data$Gender, data$AgeGroup))
4.Logistic Regression
Logistic regression is used when the response variable is binary (e.g., yes/no, success/failure). It models the probability of an outcome as a function of predictor variables.
# Example logistic regression
# Assuming 'Outcome' is a binary factor in the dataset
model <- glm(Outcome ~ Gender + AgeGroup, data = data, family = "binomial")
summary(model)
5.Ordinal Logistic Regression
For ordinal response variables, ordinal logistic regression (proportional odds model) is used. This method considers the order of categories.
# Example ordinal logistic regression using the MASS package
library(MASS)
# Assuming 'Satisfaction' is an ordinal factor
model <- polr(Satisfaction ~ Gender + AgeGroup, data = data, method = "logistic")
summary(model)
6.Multinomial Logistic Regression
When dealing with nominal response variables with more than two categories, multinomial logistic regression is appropriate.
# Example using the nnet package
library(nnet)
# Assuming 'Choice' is a nominal factor with multiple levels
model <- multinom(Choice ~ Gender + AgeGroup, data = data)
summary(model)
7. Visualizing Categorical Data
Visualization aids in interpreting results and identifying patterns. Common plots include bar charts, mosaic plots, and association plots.
# Mosaic plot
mosaicplot(table(data$Gender, data$AgeGroup), main = "Mosaic Plot of Gender vs Age Group")
Conclusion
R provides a comprehensive suite of tools for analyzing categorical data, from simple frequency tables to complex logistic regression models. By understanding the nature of your categorical variables and selecting the appropriate analytical techniques, you can uncover valuable insights from your data.
This guide provides a foundation for analyzing categorical data with R, highlighting the importance of proper data handling, statistical testing, and visualization techniques.
Introduction to Python for Geographic Data Analysis: In the realm of data science, Python has emerged as a versatile and powerful tool, finding applications across various domains. One such domain where Python shines is Geographic Data Analysis. As geospatial data becomes increasingly prevalent, the ability to analyze and interpret this data is essential. Python, with its robust ecosystem of libraries, provides an excellent platform for geographic data analysis, enabling users to perform tasks ranging from simple data manipulation to complex spatial computations and visualizations. This blog aims to introduce you to the basics of using Python for geographic data analysis, exploring the essential libraries, tools, and concepts.
Understanding Geographic Data
Before diving into Python, it’s crucial to understand what geographic data is. Geographic data, also known as geospatial data, refers to information that describes the locations and characteristics of features on Earth. This data is often represented in two forms:
Vector Data: This consists of points, lines, and polygons that represent different features like cities, rivers, and country boundaries. Each feature can have associated attributes, such as population for cities or length for rivers.
Raster Data: This represents data in a grid format, with each cell containing a value. Examples include satellite imagery, elevation data, and land cover classifications.
Geographic data can be stored in various formats, such as shapefiles, GeoJSON, and raster files like GeoTIFF. The ability to handle these formats efficiently is key to effective geographic data analysis.
Python has become the language of choice for many in the geospatial community for several reasons:
Extensive Libraries: Python offers a wide range of libraries specifically designed for geospatial data analysis, such as Geopandas, Shapely, Fiona, Rasterio, and Pyproj.
Ease of Use: Python’s syntax is straightforward, making it accessible for beginners and powerful enough for advanced users.
Integration with Other Tools: Python easily integrates with other data science tools and libraries, such as Pandas for data manipulation, Matplotlib and Seaborn for visualization, and Scikit-learn for machine learning.
Community Support: Python has a vast and active community, ensuring continuous development and support, along with a wealth of tutorials and documentation.
Getting Started with Python Libraries for Geographic Data Analysis
To start with geographic data analysis in Python, it’s essential to become familiar with some key libraries that form the foundation of most geospatial workflows.
1. Geopandas
Geopandas is an extension of the popular Pandas library, specifically designed to handle spatial data. It allows you to work with spatial data as easily as you would with a regular DataFrame in Pandas. With Geopandas, you can read, write, and manipulate vector data, perform spatial operations, and conduct spatial joins.
Example:
import geopandas as gpd

# Load a shapefile
world = gpd.read_file(gpd.datasets.get_path('naturalearth_lowres'))

# Display the first few rows
print(world.head())

# Plot the data
world.plot()
2. Shapely
Shapely is a powerful library for performing geometric operations. It enables the manipulation and analysis of planar geometric objects like points, lines, and polygons. Shapely is often used in conjunction with Geopandas to perform operations such as buffering, intersection, and union.
Example:
from shapely.geometry import Point, Polygon

# Create a Point and a Polygon
point = Point(1, 1)
polygon = Polygon([(0, 0), (2, 0), (2, 2), (0, 2)])

# Check if the point is within the polygon
print(point.within(polygon))
3. Fiona
Fiona is used for reading and writing vector data files. It provides a simple and efficient interface for handling formats like shapefiles and GeoJSON, making it an essential tool for managing geospatial data.
Example:
import fiona

# Open a shapefile
with fiona.open('path_to_shapefile.shp') as src:
    for feature in src:
        print(feature)
4. Rasterio
For working with raster data, Rasterio is the go-to library. It allows you to read and write raster datasets, perform resampling, and conduct various analyses on raster data.
Example:
import rasterio

# Open a raster file
with rasterio.open('path_to_raster.tif') as src:
    print(src.profile)

    # Read the first band
    band1 = src.read(1)
5. Pyproj
Pyproj is used for performing cartographic projections and transformations. Geospatial data often comes in different coordinate reference systems (CRS), and Pyproj helps in transforming this data into a common CRS for analysis.
Example:
from pyproj import Proj, transform

# Define two coordinate systems
wgs84 = Proj(init='epsg:4326')
utm = Proj(init='epsg:32633')

# Transform a point from WGS84 to UTM
x, y = transform(wgs84, utm, 12.4924, 41.8902)
print(x, y)
Practical Example: Analyzing Geographic Data with Python
Let’s combine these libraries in a simple example where we analyze geographic data to identify regions within a specified distance from a point of interest.
Scenario: Suppose we want to identify all countries within 1000 kilometers of a given location (e.g., a city).
Steps:
Load the data: Use Geopandas to load a dataset of world countries.
Define the point of interest: Create a point representing the location.
Buffer the point: Use Shapely to create a buffer around the point.
Perform spatial join: Use Geopandas to identify countries within the buffer.
Code:
import geopandas as gpd
from shapely.geometry import Point

# Load world countries data
world = gpd.read_file(gpd.datasets.get_path('naturalearth_lowres'))

# Define the point of interest (e.g., Rome, Italy)
point = Point(12.4924, 41.8902)  # Longitude, Latitude

# Create a GeoSeries for the point
gdf_point = gpd.GeoSeries([point], crs="EPSG:4326")

# Buffer the point by 1000 km (use an appropriate projection)
gdf_point = gdf_point.to_crs(world.crs)
buffer = gdf_point.buffer(1000000)  # Buffer in meters

# Perform spatial join to find countries within the buffer
countries_within_buffer = world[world.intersects(buffer.unary_union)]

# Plot the result
ax = world.plot(color='lightgrey')
countries_within_buffer.plot(ax=ax, color='blue')
gdf_point.plot(ax=ax, color='red')
Conclusion
Python offers a comprehensive toolkit for geographic data analysis, enabling users to handle and analyze both vector and raster data with ease. Libraries like Geopandas, Shapely, Fiona, Rasterio, and Pyproj form the backbone of geospatial workflows in Python. With these tools, you can perform a wide range of tasks, from basic data manipulation to advanced spatial analysis and visualization. Whether you’re a beginner or an experienced analyst, Python provides the flexibility and power needed to unlock the full potential of geographic data.
Time series analysis is a powerful statistical technique used to analyze data that is collected over time. This type of analysis is crucial in various fields, including finance, economics, environmental science, and engineering. R, a popular open-source programming language, provides a comprehensive suite of tools for performing time series analysis, making it accessible to both beginners and experts. This article explores the fundamentals of applied time series analysis using R, covering key concepts, methodologies, and practical applications.
1. Introduction to Time Series Data
Time series data consists of observations collected sequentially over time. Unlike cross-sectional data, where observations are independent, time series data points are often correlated. This temporal correlation introduces complexities in modeling and forecasting but also allows for the identification of trends, seasonal patterns, and cyclical behaviors.
Time series data can be classified into two main types:
Univariate Time Series: A single variable is recorded over time, such as daily stock prices or monthly rainfall.
Multivariate Time Series: Multiple variables are recorded over time, such as the simultaneous recording of temperature, humidity, and wind speed.
Understanding the characteristics of time series data is essential for choosing the appropriate analytical methods. Key properties to consider include trend, seasonality, and stationarity.
2. Understanding Key Concepts in Time Series Analysis
Before diving into the practical applications of time series analysis in R, it’s important to understand some fundamental concepts:
Trend: A long-term increase or decrease in the data. Trends can be linear or non-linear and may represent underlying economic, environmental, or social changes.
Seasonality: Regular, repeating patterns within the data, often linked to specific time intervals, such as monthly or quarterly sales cycles.
Stationarity: A stationary time series has a constant mean, variance, and autocorrelation structure over time. Stationarity is a critical assumption in many time series models.
Autocorrelation: The correlation of a time series with its own past values. High autocorrelation indicates that past values have a strong influence on future values.
R provides several packages for time series analysis, including ts, forecast, zoo, and xts. The first step in any time series analysis is to import and prepare the data.
# Import data data <- ts(read.csv("your_data.csv")$column_name, frequency=12, start=c(2020,1))
# Plot the time series plot(data, main="Time Series Data", xlab="Time", ylab="Values")
Here, the ts() function is used to create a time series object in R. The frequency parameter indicates the number of observations per unit time (e.g., 12 for monthly data), and start specifies the starting point.
4. Decomposing Time Series
Decomposing a time series involves breaking it down into its constituent components: trend, seasonality, and residuals (irregular components). This is a crucial step in understanding the underlying patterns in the data.
# Decompose the time series
decomposed <- decompose(data)

# Plot the decomposed components
plot(decomposed)
The decompose() function in R returns an object that includes the trend, seasonal, and random components. Visualizing these components helps in understanding the underlying structure of the time series.
5. Stationarity and Differencing
Most time series models require the data to be stationary. If the series is not stationary, it needs to be transformed. One common method of achieving stationarity is differencing, where the difference between consecutive observations is computed.
# Check for stationarity using Augmented Dickey-Fuller Test
adf.test(data)

# Difference the time series
diff_data <- diff(data)

# Plot the differenced data
plot(diff_data, main="Differenced Time Series", xlab="Time", ylab="Differenced Values")
The adf.test() function performs the Augmented Dickey-Fuller test, which checks for the presence of a unit root in the time series. If the p-value is low, the series is stationary; otherwise, differencing may be required.
6. Building Time Series Models
Once the time series is stationary, various models can be applied to forecast future values. Some of the most commonly used models include:
Autoregressive Integrated Moving Average (ARIMA): ARIMA is a popular model that combines autoregression (AR), differencing (I), and moving averages (MA) to model time series data.
Seasonal Decomposition of Time Series by Loess (STL): STL is a flexible method for decomposing time series that allows for seasonality and trend extraction.
# Forecast using the STL model stl_forecast <- forecast(stl_model, h=12)
# Plot the forecast plot(stl_forecast)
Each model has its strengths and weaknesses, and the choice of model depends on the characteristics of the data.
7. Evaluating Model Performance
Evaluating the accuracy of the time series model is critical for ensuring reliable forecasts. Common evaluation metrics include:
Mean Absolute Error (MAE)
Mean Squared Error (MSE)
Root Mean Squared Error (RMSE)
Mean Absolute Percentage Error (MAPE)
# Calculate accuracy metrics for ARIMA model
accuracy(forecasted)

# Calculate accuracy metrics for ETS model
accuracy(ets_forecast)
These metrics provide insights into the model’s performance and help in comparing different models.
8. Practical Applications of Time Series Analysis in R
Time series analysis in R can be applied to a wide range of practical problems, including:
Forecasting Stock Prices: Predicting future stock prices based on historical data.
Sales Forecasting: Estimating future sales to optimize inventory and production planning.
Weather Prediction: Analyzing temperature, precipitation, and other weather-related data for forecasting.
Economic Indicators: Modeling and forecasting economic indicators like GDP, unemployment rates, and inflation.
By applying the techniques discussed above, analysts can gain valuable insights into temporal data and make informed decisions.
9. Conclusion
Applied time series analysis is a critical skill for data scientists, statisticians, and analysts across various domains. R, with its rich set of packages and functions, provides a powerful platform for performing time series analysis. By understanding the key concepts, preparing data appropriately, selecting suitable models, and evaluating their performance, practitioners can harness the full potential of time series analysis to solve real-world problems. Whether you’re forecasting stock prices, predicting sales, or analyzing weather patterns, R offers the tools needed to achieve accurate and reliable results.
In the realm of data science, understanding statistical methods is crucial for analyzing and interpreting data. Python, with its rich ecosystem of libraries, provides powerful tools for performing various statistical analyses. This article explores applied univariate, bivariate, and multivariate statistics using Python, illustrating how these methods can be employed to extract meaningful insights from data.
Univariate Statistics
Definition
Univariate statistics involve the analysis of a single variable. The goal is to describe the central tendency, dispersion, and shape of the data distribution.
Descriptive Statistics
Descriptive statistics summarize and describe the features of a dataset. Key measures include:
Mean: The average value.
Median: The middle value when data is sorted.
Mode: The most frequent value.
Variance: The spread of the data.
Standard Deviation: The dispersion of data points from the mean.
# Density plot sns.kdeplot(data, shade=True) plt.title('Density Plot') plt.show()
Bivariate Statistics
Definition
Bivariate statistics involve the analysis of two variables to understand the relationship between them. This can include correlation, regression analysis, and more.
Correlation
Correlation measures the strength and direction of the linear relationship between two variables.
Example in Python
import pandas as pd
# Sample data data = {'x': [1, 2, 3, 4, 5], 'y': [2, 3, 5, 7, 11]} df = pd.DataFrame(data)
# Summary of regression analysis print(model.summary())
Visualization
Visualizing bivariate data can reveal patterns and relationships. Common plots include scatter plots and regression lines.
# Scatter plot with regression line
sns.regplot(x='x', y='y', data=df)
plt.title('Scatter Plot with Regression Line')
plt.show()
Multivariate Statistics
Definition
Multivariate statistics involve the analysis of more than two variables simultaneously. This includes techniques like multiple regression, principal component analysis (PCA), and cluster analysis.
Multiple Regression
Multiple regression analysis estimates the relationship between a dependent variable and multiple independent variables.
Applied univariate, bivariate, and multivariate statistics are essential for analyzing data in various fields. Python, with its robust libraries, offers a comprehensive toolkit for performing these analyses. By understanding and utilizing these statistical methods, data scientists can extract valuable insights and make informed decisions based on their data.
In today’s data-driven world, the role of statistics in environmental science has become indispensable. Researchers and practitioners alike harness the power of statistical data analysis to understand complex environmental phenomena, make predictions, and inform policy decisions. This article delves into the intricacies of applied environmental statistics using R, a powerful statistical software environment. We will explore key concepts, methodologies, and practical applications to illustrate how R can be effectively utilized for environmental data analysis.
Introduction to Environmental Statistics
Environmental statistics involves the application of statistical methods to environmental science issues. It covers a broad spectrum of topics, including air and water quality, climate change, biodiversity, and pollution. The main goal is to analyze and interpret data to understand environmental processes and inform decision-making.
Importance of Environmental Statistics
Data-Driven Decisions: Informs policy and management decisions based on empirical evidence.
Trend Analysis: Identifies trends and patterns in environmental data over time.
Predictive Modeling: Forecasts future environmental conditions under different scenarios.
Risk Assessment: Evaluates the risk and impact of environmental hazards.
Role of R in Environmental Statistics
R is a versatile and powerful tool widely used in environmental statistics for data analysis, visualization, and modeling. It offers numerous packages specifically designed for environmental data, making it an ideal choice for researchers and analysts.
Regression analysis explores the relationship between dependent and independent variables. It is crucial for modeling and predicting environmental data.
Linear Regression: Models the relationship between two continuous variables.
Logistic Regression: Models the relationship between a dependent binary variable and one or more independent variables.
Example in R:
# Linear Regression
model <- lm(y ~ x, data = dataset)
summary(model)

# Logistic Regression
logit_model <- glm(binary_outcome ~ predictor, data = dataset, family = "binomial")
summary(logit_model)
Time series analysis is essential for examining data collected over time. It helps in understanding trends, seasonal patterns, and forecasting future values.
Decomposition: Separates a time series into trend, seasonal, and irregular components.
ARIMA Models: Combines autoregressive and moving average components for time series forecasting.
In R, the forecast package is widely used for time series analysis:
library(forecast)
fit <- auto.arima(time_series_data)
forecast(fit, h = 10)
Applied Environmental Statistics with R: Case Studies
Case Study 1: Air Quality Monitoring
Air quality monitoring involves collecting data on pollutants such as particulate matter (PM2.5), nitrogen dioxide (NO2), and sulfur dioxide (SO2). Statistical analysis of this data helps in assessing pollution levels and identifying sources.
Data Collection and Preparation
Data can be collected from various sources, such as government monitoring stations or satellite observations. The first step is to clean and prepare the data:
Climate change analysis often involves studying temperature and precipitation data over extended periods. Statistical methods help in detecting trends and making future projections.
Data Collection and Preparation
Temperature data can be sourced from meteorological stations or global climate databases. Data preparation involves cleaning and transforming the data into a suitable format for analysis:
# Load temperature data temp_data <- read.csv("temperature_data.csv")
Forecasting future temperatures using ARIMA models:
temp_fit <- auto.arima(temp_ts)
future_temp <- forecast(temp_fit, h = 120)
plot(future_temp)
Case Study 3: Biodiversity Assessment
Biodiversity assessment involves analyzing species abundance and distribution data to understand ecological patterns and processes.
Data Collection and Preparation
Species data is often collected through field surveys or remote sensing. Data preparation involves cleaning and organizing the data for analysis:
# Load biodiversity data
biodiversity_data <- read.csv("biodiversity_data.csv")

# Data cleaning
biodiversity_data <- biodiversity_data %>%
  filter(!is.na(SpeciesCount)) %>%
  mutate(Date = ymd(Date))
Statistical Analysis
Assessing species richness and diversity:
library(vegan)

# Calculate species richness
species_richness <- specnumber(biodiversity_data$SpeciesCount)

# Calculate Shannon diversity index
shannon_diversity <- diversity(biodiversity_data$SpeciesCount, index = "shannon")
Conclusion
Statistical data analysis plays a critical role in understanding and addressing environmental issues. R, with its extensive range of packages and functions, provides a robust platform for conducting environmental statistics. Whether monitoring air quality, analyzing climate change, or assessing biodiversity, R offers the tools needed to turn data into actionable insights. By leveraging these tools, environmental scientists and policymakers can make informed decisions that promote sustainability and protect our natural world.
Data analysis has become an essential skill in today’s data-driven world. Whether you are a data scientist, analyst, or business professional, understanding how to manipulate and analyze data can provide valuable insights. Two powerful Python libraries widely used for data analysis are NumPy and pandas. This article will explore how to use these tools to perform hands-on data analysis.
Introduction to NumPy
NumPy, short for Numerical Python, is a fundamental package for scientific computing in Python. It provides support for arrays, matrices, and a large number of mathematical functions. NumPy arrays are more efficient and convenient than traditional Python lists for numerical operations.
Key Features of NumPy
Array Creation: NumPy allows easy creation of arrays, including multi-dimensional arrays.
Mathematical Operations: Perform element-wise operations, linear algebra, and more.
Random Sampling: Generate random numbers for simulations and testing.
Integration with Other Libraries: Works seamlessly with other scientific computing libraries like SciPy, pandas, and matplotlib.
pandas is a powerful, open-source data analysis and manipulation library for Python. It provides data structures like Series and DataFrame, which make data handling and manipulation easy and intuitive.
Key Features of pandas
Data Structures: Series and DataFrame for handling one-dimensional and two-dimensional data, respectively.
Data Manipulation: Tools for filtering, grouping, merging, and reshaping data.
Handling Missing Data: Functions to detect and handle missing data.
Time Series Analysis: Built-in support for time series data.
Creating and Manipulating DataFrames
First, install pandas using pip:
pip install pandas
Here’s an example of creating and manipulating a pandas DataFrame:
NumPy and pandas are often used together in data analysis workflows. NumPy provides the underlying data structures and numerical operations, while pandas offers higher-level data manipulation tools.
Example: Analyzing a Dataset
Let’s analyze a dataset using both NumPy and pandas. We’ll use the famous Iris dataset, which contains measurements of different iris flowers.
import numpy as np
import pandas as pd
from sklearn.datasets import load_iris

# Load the Iris dataset
iris = load_iris()
data = iris.data
columns = iris.feature_names
df = pd.DataFrame(data, columns=columns)

# Summary statistics using pandas
print("Summary Statistics:\n", df.describe())

# NumPy operations on DataFrame
sepal_length = df['sepal length (cm)'].values
print("Mean Sepal Length:", np.mean(sepal_length))
print("Median Sepal Length:", np.median(sepal_length))
print("Standard Deviation of Sepal Length:", np.std(sepal_length))
Advanced Data Manipulation with pandas
pandas provides a rich set of functions for data manipulation, including grouping, merging, and pivoting data.
Grouping Data
Grouping data is useful for performing aggregate operations on subsets of data.
# Group by 'City' and calculate the mean age
grouped_df = df.groupby('City')['Age'].mean()
print("Mean Age by City:\n", grouped_df)
Merging DataFrames
Merging is useful for combining data from multiple sources.
Data visualization is crucial for understanding and communicating data insights. While NumPy and pandas provide basic plotting capabilities, integrating them with libraries like matplotlib and seaborn enhances visualization capabilities.
import matplotlib.pyplot as plt
import seaborn as sns

# Basic plot with pandas
df['Age'].plot(kind='hist', title='Age Distribution')
plt.show()

# Advanced plot with seaborn
sns.pairplot(df)
plt.show()
Conclusion
Hands-on data analysis with NumPy and pandas enables you to efficiently handle, manipulate, and analyze data. NumPy provides powerful numerical operations, while pandas offer high-level data manipulation tools. By combining these libraries, you can perform complex data analysis tasks with ease. Whether you are exploring datasets, performing statistical analysis, or preparing data for machine learning, NumPy and pandas are indispensable tools in your data analysis toolkit.
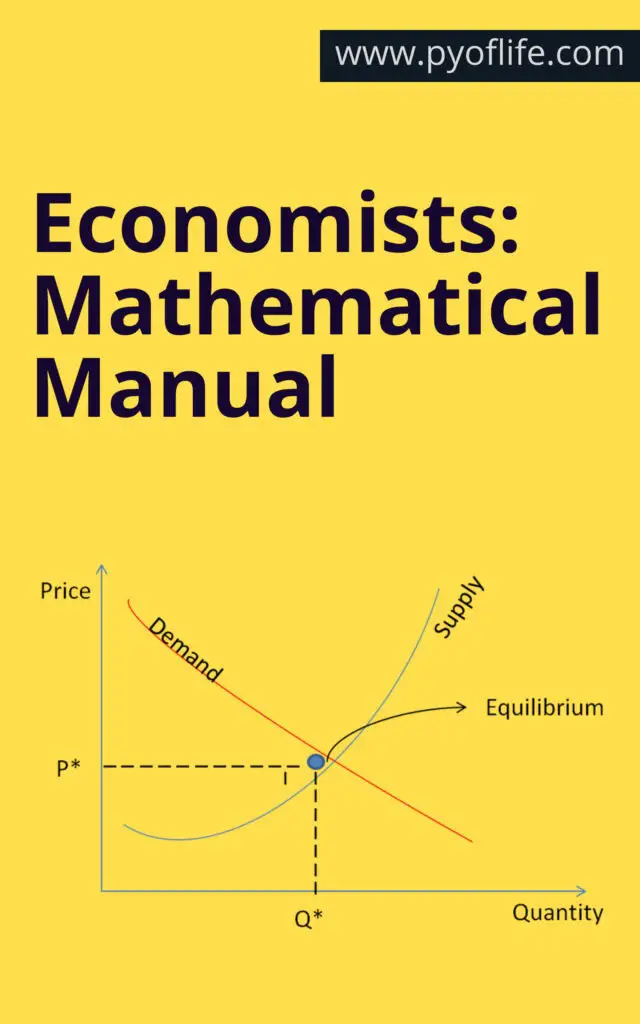
Economists: Mathematical Manual: Economics, often dubbed the “dismal science,” is far more vibrant and dynamic than this moniker suggests. At its core, economics is the study of how societies allocate scarce resources among competing uses. To understand and predict these allocations, economists rely heavily on mathematical tools and techniques. This article provides a comprehensive guide to the essential mathematical concepts and methods used in economics, aiming to serve as a handy reference for students, professionals, and enthusiasts alike.
Mathematics provides a formal framework for analyzing economic theories and models. It helps in deriving precise conclusions from assumptions and in rigorously testing hypotheses. The quantitative nature of economics makes mathematics indispensable for:
Formulating economic theories.
Analyzing data and interpreting results.
Making predictions about economic behavior.
Conducting policy analysis and evaluation.
Key Mathematical Concepts in Economics
1. Algebra and Linear Equations
Algebra forms the backbone of most economic analyses. Linear equations are particularly crucial as they represent relationships between variables in a simplified manner.
Example: The supply and demand functions in a market can be expressed as linear equations:
Qd=a−bPQ_d = a – bPQd=a−bP (Demand function)
Qs=c+dPQ_s = c + dPQs=c+dP (Supply function)
Where QdQ_dQd is the quantity demanded, QsQ_sQs is the quantity supplied, PPP is the price, and aaa, bbb, ccc, and ddd are parameters.
Calculus, particularly differentiation and integration, is fundamental in economics for understanding changes and trends.
Differentiation helps in finding the rate of change of economic variables. For example, marginal cost and marginal revenue are derivatives of cost and revenue functions, respectively.
Integration is used for aggregating economic quantities, such as finding total cost from marginal cost.
Example: If the total cost function is C(Q)=100+10Q+0.5Q2C(Q) = 100 + 10Q + 0.5Q^2C(Q)=100+10Q+0.5Q2, the marginal cost (MC) is the derivative MC=dCdQ=10+QMC = \frac{dC}{dQ} = 10 + QMC=dQdC=10+Q.
3. Optimization
Optimization techniques are crucial for decision-making in economics. Economists often seek to maximize or minimize objective functions subject to certain constraints.
Unconstrained Optimization: Solving problems without restrictions, typically by setting the derivative equal to zero to find critical points.
Constrained Optimization: Involves using methods like Lagrange multipliers to handle constraints.
Example: A firm wants to maximize its profit π=TR−TC\pi = TR – TCπ=TR−TC, where TRTRTR is total revenue and TCTCTC is the total cost. By differentiating π\piπ concerning quantity and setting it to zero, we find the optimal output level.
4. Matrix Algebra
Matrix algebra is used extensively in econometrics, input-output analysis, and in solving systems of linear equations.
Econometrics: Matrices simplify the representation and solution of multiple regression models.
Input-Output Analysis: Leontief models use matrices to describe the flow of goods and services in an economy.
Example: A simple econometric model can be written in matrix form as Y=Xβ+ϵY = X\beta + \epsilonY=Xβ+ϵ, where YYY is the vector of observations, XXX is the matrix of explanatory variables, β\betaβ is the vector of coefficients, and ϵ\epsilonϵ is the error term.
Econometric Techniques
Econometrics combines economic theory, mathematics, and statistical inference to quantify economic phenomena. Some essential techniques include:
1. Regression Analysis
Regression analysis estimates the relationships between variables. The most common is the Ordinary Least Squares (OLS) method.
Example: Estimating the consumption function C=α+βY+uC = \alpha + \beta Y + uC=α+βY+u, where CCC is consumption, YYY is income, and uuu is the error term.
2. Time Series Analysis
Time series analysis deals with data collected over time, essential for analyzing economic trends and forecasting.
Autoregressive (AR) Models: Explain a variable using its past values.
Moving Average (MA) Models: Use past forecast errors.
ARIMA Models: Combine AR and MA models to handle non-stationary data.
Example: GDP forecasting using an ARIMA model involves identifying the order of the model and estimating parameters to predict future values.
3. Panel Data Analysis
Panel data combines cross-sectional and time-series data, allowing for more complex analyses and control of individual heterogeneity.
Example: Studying the impact of education on earnings using data from multiple individuals over several years.
Game Theory
Game theory analyzes strategic interactions where the outcome depends on the actions of multiple agents. Key concepts include:
Nash Equilibrium: A situation where no player can benefit by changing their strategy unilaterally.
Dominant Strategies: A strategy that yields a better outcome regardless of what others do.
Example: The Prisoner’s Dilemma illustrates how rational individuals might not cooperate, even if it appears that cooperation would be beneficial.
Dynamic Programming
Dynamic programming solves complex problems by breaking them down into simpler sub-problems. It is particularly useful in macroeconomics and finance for:
Optimal Control Theory: Managing economic systems over time.
Bellman Equation: A recursive equation used in dynamic programming.
Example: Determining optimal investment strategies over time by maximizing the expected utility of consumption.
Economists: Mathematical Manual
Conclusion: Mathematics is the language through which economists describe, analyze, and interpret economic phenomena. From basic algebra to advanced econometric techniques, mathematical tools are indispensable for anyone seeking to understand or contribute to economics. This manual provides a glimpse into the essential mathematical methods used in economics. Still, continuous learning and practice are necessary to master these tools and apply them effectively in real-world scenarios.
Data science is a rapidly evolving field that leverages various techniques and tools to extract insights from data. R, a powerful and versatile programming language, is extensively used in data science for its statistical capabilities and comprehensive package ecosystem. This guide provides a detailed exploration of practical data science with R, from basic syntax to advanced machine learning and deployment.
What is Data Science?
Definition and Scope
Data science involves the use of algorithms, data analysis, and machine learning to interpret complex data and derive meaningful insights. It intersects various disciplines, including statistics, computer science, and domain-specific knowledge, to solve real-world problems.
Importance in Various Fields
Data science plays a crucial role across different sectors such as healthcare, finance, marketing, and government. It aids in making informed decisions, improving operational efficiency, and providing personalized experiences.
Overview of R Programming Language
History and Evolution
R was developed in the early 1990s by Ross Ihaka and Robert Gentleman at the University of Auckland, New Zealand. It evolved from the S language, becoming a favorite among statisticians and data miners for its extensive statistical libraries.
Why Choose R for Data Science?
R is favored for data science due to its vast array of packages, strong community support, and its powerful data handling and visualization capabilities. It excels in statistical analysis, making it a go-to tool for data scientists.
To begin with R, download and install R from CRAN (Comprehensive R Archive Network). For an enhanced development experience, install RStudio, an integrated development environment (IDE) that simplifies coding in R.
Configuring R for Data Science Projects
Proper configuration involves setting up necessary packages and libraries, customizing the IDE settings, and organizing your workspace for efficient project management.
Basic R Syntax and Data Types
Variables and Data Types
In R, data types include vectors, lists, matrices, data frames, and factors. Variables are created using the assignment operator <-. Understanding these basics is crucial for effective data manipulation and analysis.
Basic Operations in R
Basic operations involve arithmetic calculations, logical operations, and data manipulation techniques. Mastering these operations lays the foundation for more complex analyses.
Data Manipulation with dplyr
Introduction to dplyr
dplyr is a powerful package for data manipulation in R. It simplifies data cleaning and transformation with its intuitive syntax and robust functions.
Data Cleaning and Transformation
Using dplyr, data cleaning and transformation become streamlined tasks. Functions like filter(), select(), mutate(), and arrange() are essential for preparing data for analysis.
Aggregation and Summarization
dplyr also excels in aggregating and summarizing data. Functions such as summarize() and group_by() allow for efficient data summarization and insights extraction.
ggplot2, an R package, is renowned for its elegant and versatile data visualization capabilities. It follows the grammar of graphics, making it highly flexible and customizable.
Creating Various Types of Plots
With ggplot2, you can create a variety of plots, including scatter plots, line graphs, bar charts, and histograms. Each plot type serves different analytical purposes and helps in visual data exploration.
Customizing Plots
Customization in ggplot2 is extensive. You can modify plot aesthetics, themes, and scales to enhance the visual appeal and clarity of your data visualizations.
Descriptive statistics involve summarizing and describing the features of a dataset. R provides functions to calculate mean, median, mode, standard deviation, and other summary statistics.
Inferential Statistics
Inferential statistics allow you to make predictions or inferences about a population based on sample data. Techniques include confidence intervals, regression analysis, and ANOVA.
Hypothesis Testing
Hypothesis testing in R involves testing assumptions about data. Common tests include t-tests, chi-square tests, and ANOVA, which help in validating scientific hypotheses.
Machine learning (ML) in R involves using algorithms to build predictive models. R’s ML capabilities are enhanced by packages such as caret, randomForest, and xgboost.
Supervised Learning Algorithms
Supervised learning involves training a model on labeled data. Common algorithms include linear regression, logistic regression, decision trees, and support vector machines.
Unsupervised Learning Algorithms
Unsupervised learning deals with unlabeled data to find hidden patterns. Algorithms such as k-means clustering and principal component analysis (PCA) are widely used.
Text Mining and Natural Language Processing
Introduction to Text Mining
Text mining involves extracting meaningful information from text data. R provides several packages like tm and text mining tools for this purpose.
Techniques for Text Analysis
Text analysis techniques include tokenization, stemming, and lemmatization. These methods help in transforming raw text into analyzable data.
Sentiment Analysis
Sentiment analysis involves determining the sentiment expressed in a text. R packages like syuzhet and sentimentr facilitate this analysis, providing insights into public opinion.
Time series data is data that is collected at successive points in time. Understanding its characteristics is crucial for effective analysis and forecasting.
Forecasting Methods
Forecasting methods in R include ARIMA, exponential smoothing, and neural networks. These methods predict future values based on historical data.
Evaluating Forecast Accuracy
Evaluating the accuracy of forecasts involves using metrics like Mean Absolute Error (MAE) and Root Mean Squared Error (RMSE). These metrics assess the model’s predictive performance.
Working with Big Data in R
Introduction to Big Data Concepts
Big data involves large and complex datasets that traditional data processing techniques cannot handle. R’s integration with big data technologies makes it a valuable tool for big data analysis.
R Packages for Big Data
R packages such as dplyr, data.table, and sparklyr enable efficient handling and analysis of big data. These packages provide tools for data manipulation, visualization, and modeling.
Case Studies and Applications
Case studies in big data illustrate the practical applications of R in handling large datasets. Examples include analyzing social media data and sensor data from IoT devices.
Deploying Data Science Models
Introduction to Model Deployment
Model deployment involves putting machine learning models into production. This step is crucial for delivering actionable insights in real-time applications.
Tools and Techniques
R provides several tools for model deployment, including Shiny for web applications and plumber for creating APIs. These tools facilitate the integration of models into operational systems.
Case Studies
Case studies in model deployment showcase real-world applications. Examples include deploying predictive models in finance for credit scoring and in healthcare for patient diagnosis.
Collaborating and Sharing Work
Version Control with Git
Version control with Git is essential for collaborative data science projects. It allows multiple users to work on the same project simultaneously and maintain a history of changes.
Sharing Work through R Markdown
R Markdown enables the creation of dynamic documents that combine code, output, and narrative. It is an excellent tool for sharing reproducible research and reports.
Collaborating with Teams
Collaboration tools such as GitHub, Slack, and project management software enhance teamwork. Effective communication and project planning are key to successful data science projects.
Best Practices in Data Science Projects
Project Planning and Management
Effective project planning and management ensure that data science projects are completed on time and within budget. This involves defining clear goals, timelines, and deliverables.
Ethical Considerations
Ethical considerations in data science include data privacy, bias, and fairness. Adhering to ethical guidelines is crucial for maintaining trust and credibility.
Continuous Learning and Improvement
Continuous learning and improvement involve staying updated with the latest developments in data science. This includes attending conferences, taking courses, and participating in professional communities.
In healthcare, data science applications include predictive analytics for patient outcomes, personalized medicine, and operational efficiency improvements.
Case Study 2: Finance
In finance, data science is used for credit scoring, fraud detection, and algorithmic trading. These applications help in managing risks and optimizing investment strategies.
Case Study 3: Marketing
In marketing, data science aids in customer segmentation, sentiment analysis, and campaign optimization. It helps in understanding customer behavior and enhancing marketing effectiveness.
Advanced statistical methods include multivariate analysis, Bayesian statistics, and survival analysis. These methods address complex data scenarios and provide deeper insights.
Advanced Machine Learning Techniques
Advanced machine learning techniques involve deep learning, reinforcement learning, and ensemble methods. These techniques improve model accuracy and performance.
Specialized Packages and Tools
Specialized packages and tools in R cater to specific data science needs. Examples include Bioconductor for bioinformatics and rpart for recursive partitioning.
Resources for Learning R and Data Science
Books and Online Courses
Books and online courses provide structured learning paths for mastering R and data science. Popular resources include “R for Data Science” by Hadley Wickham and Coursera courses.
Communities and Forums
Communities and forums such as RStudio Community, Stack Overflow, and Kaggle offer support and knowledge sharing. Participating in these communities helps in solving problems and staying updated.
Continuous Learning Paths
Continuous learning paths involve a mix of formal education, online courses, and self-study. Keeping abreast of the latest research and trends is essential for career growth in data science.
Conclusion: Practical Data Science with R
Practical data science with R encompasses a wide range of techniques and tools for data manipulation, visualization, statistical analysis, machine learning, and deployment. Mastery of R provides a strong foundation for solving complex data problems and deriving actionable insights.
In today’s data-driven world, machine learning has become an indispensable tool across various industries. Machine learning algorithms allow systems to learn and make decisions from data without being explicitly programmed. This article explores pro machine learning algorithms, shedding light on their types, applications, and best practices for implementation.
What Are Machine Learning Algorithms?
Machine learning algorithms are computational methods that enable machines to identify patterns, learn from data, and make decisions or predictions. They are the backbone of artificial intelligence, powering applications ranging from simple email filtering to complex autonomous driving systems.
Types of Machine Learning Algorithms
Machine learning algorithms can be categorized into four main types: supervised learning, unsupervised learning, semi-supervised learning, and reinforcement learning. Each type has its own unique methodologies and applications.
Supervised learning algorithms are trained on labeled data, where the input and output are known. They are used for classification and regression tasks.
Linear Regression
Logistic Regression
Decision Trees
Support Vector Machines (SVM)
Neural Networks
Unsupervised Learning
Unsupervised learning algorithms deal with unlabeled data, finding hidden patterns and structures within the data.
K-Means Clustering
Hierarchical Clustering
Principal Component Analysis (PCA)
Independent Component Analysis (ICA)
Semi-Supervised Learning
Semi-supervised learning combines labeled and unlabeled data to improve learning accuracy.
Reinforcement learning algorithms learn by interacting with the environment, receiving rewards or penalties based on actions taken.
Q-Learning
Deep Q-Network (DQN)
Policy Gradient Methods
Actor-Critic Methods
Supervised Learning Algorithms
Supervised learning involves using known input-output pairs to train models that can predict outputs for new inputs. Here are some key supervised learning algorithms:
Linear Regression
Linear regression is used for predicting continuous values. It assumes a linear relationship between the input variables (features) and the single output variable (label).
Logistic Regression
Logistic regression is a classification algorithm used to predict the probability of a binary outcome. It uses a logistic function to model the relationship between the features and the probability of a particular class.
Decision Trees
Decision trees split the data into subsets based on feature values, creating a tree-like model of decisions. They are simple to understand and interpret, making them popular for classification and regression tasks.
Support Vector Machines (SVM)
SVMs are used for classification by finding the hyperplane that best separates the classes in the feature space. They are effective in high-dimensional spaces and for cases where the number of dimensions exceeds the number of samples.
Neural Networks
Neural networks are a series of algorithms that mimic the operations of a human brain to recognize patterns. They consist of layers of neurons, where each layer processes input data and passes it to the next layer.
Unsupervised Learning Algorithms
Unsupervised learning algorithms are used to find hidden patterns in data without pre-existing labels.
K-Means Clustering
K-Means clustering partitions the data into K distinct clusters based on feature similarity. It is widely used for market segmentation, image compression, and more.
Hierarchical Clustering
Hierarchical clustering builds a hierarchy of clusters either through a bottom-up (agglomerative) or top-down (divisive) approach. It is useful for data with nested structures.
Principal Component Analysis (PCA)
PCA reduces the dimensionality of data by transforming it into a new set of variables (principal components) that are uncorrelated and capture the maximum variance in the data.
Independent Component Analysis (ICA)
ICA is used to separate a multivariate signal into additive, independent components. It is often used in signal processing and for identifying hidden factors in data.
Semi-Supervised Learning Algorithms
Semi-supervised learning is a hybrid approach that uses both labeled and unlabeled data to improve learning outcomes.
Self-Training
In self-training, a model is initially trained on a small labeled dataset, and then it labels the unlabeled data. The newly labeled data is added to the training set, and the process is repeated.
Co-Training
Co-training involves training two models on different views of the same data. Each model labels the unlabeled data, and the most confident predictions are added to the training set of the other model.
Multi-View Learning
Multi-view learning uses multiple sources or views of data to improve learning performance. Each view provides different information about the instances, enhancing the learning process.
Reinforcement Learning Algorithms
Reinforcement learning algorithms learn by interacting with their environment and receiving feedback in the form of rewards or penalties.
Q-Learning
Q-Learning is a model-free reinforcement learning algorithm that aims to learn the quality of actions, telling an agent what action to take under what circumstances.
Deep Q-Network (DQN)
DQN combines Q-Learning with deep neural networks, enabling it to handle large and complex state spaces. It has been successful in applications like playing video games.
Policy Gradient Methods
Policy gradient methods directly optimize the policy by gradient ascent, improving the probability of taking good actions. They are effective in continuous action spaces.
Actor-Critic Methods
Actor-Critic methods combine policy gradients and value-based methods, where the actor updates the policy and the critic evaluates the action taken by the actor, improving learning efficiency.
Deep learning algorithms are a subset of machine learning that involve neural networks with many layers, enabling them to learn complex patterns in large datasets.
Convolutional Neural Networks (CNN)
CNNs are designed for processing structured grid data like images. They use convolutional layers to automatically and adaptively learn spatial hierarchies of features.
Recurrent Neural Networks (RNN)
RNNs are used for sequential data as they have connections that form cycles, allowing information to persist. They are widely used in natural language processing.
Long Short-Term Memory (LSTM)
LSTMs are a type of RNN that can learn long-term dependencies, solving the problem of vanishing gradients in traditional RNNs. They are effective in tasks like language modeling and time series prediction.
Generative Adversarial Networks (GANs)
GANs consist of two neural networks, a generator, and a discriminator, that compete with each other. The generator creates data, and the discriminator evaluates its authenticity, leading to high-quality data generation.
Ensemble Learning Algorithms
Ensemble learning combines multiple models to improve prediction performance and robustness.
Bagging
Bagging (Bootstrap Aggregating) reduces variance by training multiple models on different subsets of the data and averaging their predictions. Random Forests are a popular bagging method.
Boosting
Boosting sequentially trains models, each correcting the errors of its predecessor. It focuses on hard-to-predict cases, improving accuracy. Examples include AdaBoost and Gradient Boosting.
Stacking
Stacking combines multiple models by training a meta-learner to make final predictions based on the predictions of base models, enhancing predictive performance.
Evaluating Machine Learning Models
Evaluating machine learning models is crucial to understand their performance and reliability.
Accuracy
Accuracy measures the proportion of correct predictions out of all predictions. It is suitable for balanced datasets but may be misleading for imbalanced ones.
Precision and Recall
Precision measures the proportion of true positive predictions among all positive predictions, while recall measures the proportion of true positive predictions among all actual positives. They are crucial for imbalanced datasets.
F1 Score
The F1 Score is the harmonic mean of precision and recall, providing a balanced measure for evaluating model performance, especially in imbalanced datasets.
ROC-AUC Curve
The ROC-AUC curve plots the true positive rate against the false positive rate, and the area under the curve (AUC) measures the model’s ability to distinguish between classes.
Choosing the Right Algorithm
Choosing the right machine learning algorithm depends on several factors:
Problem Type
Different algorithms are suited for classification, regression, clustering, or dimensionality reduction problems. The nature of the problem dictates the algorithm choice.
Data Size
Some algorithms perform better with large datasets, while others are suitable for smaller datasets. Consider the data size when selecting an algorithm.
Interpretability
Interpretability is crucial in applications where understanding the decision-making process is important. Simple algorithms like decision trees are more interpretable than complex ones like deep neural networks.
Training Time
The computational resources and time available for training can influence the choice of algorithm. Some algorithms require significant computational power and time to train.
Practical Applications of Machine Learning Algorithms
Machine learning algorithms are applied in various fields, solving complex problems and automating tasks.
Healthcare
In healthcare, machine learning algorithms are used for disease prediction, medical imaging, and personalized treatment plans, improving patient outcomes and operational efficiency.
Finance
In finance, algorithms are used for fraud detection, algorithmic trading, and risk management, enhancing security and profitability.
Marketing
Machine learning enhances marketing efforts through customer segmentation, personalized recommendations, and predictive analytics, driving sales and customer engagement.
Autonomous Vehicles
Autonomous vehicles rely on machine learning algorithms for navigation, object detection, and decision-making, enabling safe and efficient self-driving technology.
Challenges in Machine Learning
Despite its potential, machine learning faces several challenges.
Data Quality
The quality of data impacts the performance of machine learning models. Noisy, incomplete, or biased data can lead to inaccurate predictions.
Overfitting and Underfitting
Overfitting occurs when a model learns the training data too well, capturing noise rather than the underlying pattern. Underfitting happens when a model fails to learn the training data adequately.
Computational Resources
Training complex models, especially deep learning algorithms, requires significant computational resources, which can be a barrier for some applications.
Future Trends in Machine Learning Algorithms
The field of machine learning is rapidly evolving, with several trends shaping its future.
Explainable AI
Explainable AI aims to make machine learning models transparent and interpretable, addressing concerns about decision-making in critical applications.
Quantum Machine Learning
Quantum machine learning explores the integration of quantum computing with machine learning, promising to solve complex problems more efficiently.
Automated Machine Learning (AutoML)
AutoML automates the process of applying machine learning to real-world problems, making it accessible to non-experts and accelerating model development.
Best Practices for Implementing Machine Learning Algorithms
Implementing machine learning algorithms requires adhering to best practices to ensure successful outcomes.
Data Preprocessing
Preprocessing involves cleaning and transforming data to make it suitable for modeling. It includes handling missing values, scaling features, and encoding categorical variables.
Feature Engineering
Feature engineering involves creating new features or transforming existing ones to improve model performance. It requires domain knowledge and creativity.
Model Validation
Model validation ensures that the model generalizes well to new data. Techniques like cross-validation and train-test splits help in evaluating model performance.
Case Studies of Successful Machine Learning Implementations
Several organizations have successfully implemented machine learning, demonstrating its potential.
AlphaGo by Google DeepMind
AlphaGo, developed by Google DeepMind, used reinforcement learning and neural networks to defeat world champions in the game of Go, showcasing the power of advanced algorithms.
Netflix Recommendation System
Netflix uses collaborative filtering and deep learning algorithms to provide personalized movie and TV show recommendations, enhancing user experience and retention.
Fraud Detection by PayPal
PayPal employs machine learning algorithms to detect fraudulent transactions in real-time, improving security and reducing financial losses.
Conclusion
Pro machine learning algorithms are transforming industries by enabling intelligent decision-making and automation. Understanding their types, applications, and best practices is crucial for leveraging their full potential. As technology evolves, staying updated with trends and advancements will ensure continued success in the ever-evolving field of machine learning.
Introductory Time Series with R: Time series analysis is a powerful statistical tool used to analyze time-ordered data points. This analysis is pivotal in various fields like finance, economics, environmental science, and more. With the advent of advanced computing tools, R programming has become a popular choice for time series analysis due to its extensive libraries and user-friendly syntax. This guide will delve into the basics of time series analysis using R, providing a solid foundation for beginners and a refresher for seasoned analysts.
Understanding Time Series
Definition of Time Series
A time series is a sequence of data points collected or recorded at specific time intervals. These data points represent the values of a variable over time, enabling analysts to identify trends, patterns, and anomalies.
Components of Time Series
Trend: The long-term movement or direction in the data.
Seasonality: Regular patterns or cycles in the data occurring at specific intervals.
Cyclicity: Fluctuations in data occurring at irregular intervals, often related to economic or business cycles.
Randomness: Irregular, unpredictable variations in the data.
To start with time series analysis in R, you need to install R and RStudio. R is the programming language, and RStudio is an integrated development environment (IDE) that makes R easier to use.
Installing Required Packages
For time series analysis, several R packages are essential. Some of these include:
forecast: For forecasting time series.
tseries: For time series analysis.
xts and zoo: For handling irregular time series data.
Evaluate the performance of your time series models using metrics like Mean Absolute Error (MAE), Mean Squared Error (MSE), and Root Mean Squared Error (RMSE).
accuracy(forecasted)
Cross-Validation
Cross-validation helps in assessing how the results of a statistical analysis will generalize to an independent data set.
Time series analysis is extensively used in financial market analysis for predicting stock prices, market trends, and economic indicators.
Weather Forecasting
Meteorologists use time series analysis to predict weather patterns and climate changes.
Demand Forecasting
Businesses use time series analysis for inventory management and predicting future demand.
Challenges in Time Series Analysis
Handling Missing Data
Missing data can distort the analysis. Techniques like interpolation, forward filling, and imputation can handle missing values.
Dealing with Outliers
Outliers can significantly affect the results. Identifying and handling outliers is crucial.
Choosing the Right Model
Selecting the appropriate model depends on the data’s nature and the analysis’s specific requirements.
Conclusion: Introductory Time Series with R
Time series analysis is critical for data analysts and scientists, offering valuable insights into temporal data. With R’s powerful libraries and tools, performing time series analysis becomes more accessible and efficient. By mastering the basics and exploring advanced techniques, you can unlock the full potential of time series data to inform decisions and predictions.